
What Purchase Intent Detection Means
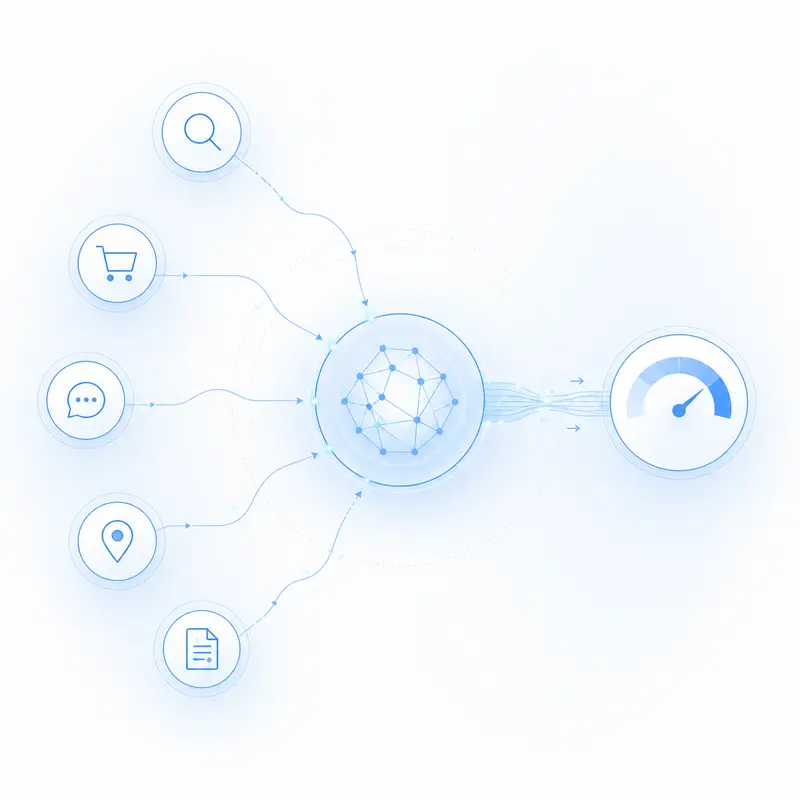
Purchase intent detection estimates how likely a prospect is to buy—and often within what timeframe—based on their observed behaviors and context across channels. It goes beyond basic behavior tracking. Tracking records events like pageviews, email clicks, or pricing page visits. Intent detection interprets those events in sequence and in context, weighs their recency and quality, and converts them into an intent score or stage that sales and marketing teams can act on.
Why this matters: teams have finite capacity. Acting on raw activity floods your workflows with noise. Acting on intent focuses effort where it has the highest probability of return. It improves efficiency by:
- Prioritizing leads and accounts with the strongest buying likelihood.
- Timing outreach to moments of peak interest instead of generic cadences.
- Tailoring messages and offers to the signals prospects actually exhibit.
- Suppressing low-intent audiences to reduce ad waste and email fatigue.
- Routing opportunities to the right owner or motion (self-serve, SDR, AE, partner) based on predicted readiness.
Common business goals supported by purchase intent detection include:
- Lead and account prioritization in the CRM.
- Qualification alignment across marketing and sales (e.g., MQL, PQL, sales-ready).
- Personalization of emails, ads, chat, and website experiences.
- Ad retargeting and suppression to optimize spend.
- Sales and CS play selection (e.g., demo vs. education vs. nurture).
- Forecasting pipeline confidence based on intent-weighted opportunities.
KatalystIQ operationalizes ai purchase intent by continuously monitoring buying signals, enriching profiles, scoring opportunities, and triggering personalized outreach and workflows. This turns intent from a report into daily action for SDRs, AEs, and marketers.
Business Value and Use Cases
Core use cases span the full revenue lifecycle:
- Ad targeting and suppression: Build high-intent audiences for prospecting and retargeting; suppress low-intent segments to lower CAC and protect sender and domain health.
- Sales outreach and routing: Push top-intent leads to SDRs with tailored talking points; route enterprise-level intent to account owners.
- ABM and key account prioritization: Focus efforts on accounts showing behavioral intent signals across multiple stakeholders.
- Website and product personalization: Adapt pages, CTAs, and in-app prompts to a visitor’s detected stage (evaluation vs. comparison vs. purchase).
- Retention, cross-sell, and upsell: Detect positive intent for adjacent products or negative intent that suggests churn risk; trigger CS actions accordingly.
- Event and webinar follow-up: Differentiate high-intent participants (e.g., engaged Q&A, pricing interest) from passive attendees.
How intent drives ROI:
- Shorter sales cycles: Timely outreach to prospects already evaluating reduces back-and-forth and accelerates consensus.
- Higher conversion rates: Messaging and offers mapped to observed needs outperform generic pitches.
- Lower acquisition costs: Suppressing low-intent audiences cuts wasted impressions and unproductive calls.
- Better pipeline quality: Forecasting and resourcing improve when intent-weighted opportunities dominate the funnel.
- Improved seller productivity: Reps spend more time with likely buyers, increasing meetings and win rates per rep.
Examples by industry:
- Ecommerce: Cart activity combined with category depth, repeat visits, and shipping calculator use signals near-term purchase; trigger limited-time offers or one-to-one assistance.
- SaaS: Pricing page revisits, documentation comparisons, seat calculator use, and trial activation events indicate evaluation; prioritize outreach and provide ROI calculators.
- B2B services: RFP downloads, case study engagement, and executive job changes at target accounts point to budgeted initiatives; align senior sellers and reference stories.
- Retail: Local inventory checks, store locator use, and repeat brand searches suggest imminent in-store visits; prompt curbside pickup or appointment scheduling.
KatalystIQ supports these motions by detecting buying signals (e.g., hiring trends, funding, technology changes), enriching and qualifying leads, and generating personalized outreach at scale—so teams can convert intent into appointments and revenue.
Signals and Data Sources
Effective purchase intent detection blends explicit, implicit, and cross-channel data into a coherent picture.
Explicit signals (high intent, directly expressed):
- Search queries and on-site search terms reflecting solution, brand, or competitor interest.
- High-value page visits: pricing, ROI, implementation, comparison, integration docs.
- Product interactions: add-to-cart, save-for-later, wishlists, quote builder, trial start, POC request.
- Form fills: demo requests, contact forms, RFP submissions, event registrations.
- Conversations: chat sessions with buying questions, booked meetings, sales call outcomes.
Implicit signals (behavioral context that suggests readiness):
- Session depth and dwell time on decision content versus top-of-funnel content.
- Repeat visits and shrinking gaps between visits.
- Scroll depth and video watch time on key pages.
- Path patterns that indicate comparison (alternating product/pricing pages) or urgency (late-night or mobile-to-desktop switch before a form fill).
- Referral quality (e.g., visitors from product review pages behaving more decisively).
Cross-channel sources that complete the picture:
- Email engagement: link clicks, replies, and conversions (opens are less reliable); unsubscribe or spam reports as negative intent.
- Ads: view-through and click-through sequences tied to on-site actions.
- CRM and sales notes: stage changes, objection themes, and last-touch outcomes.
- Customer support and chat: pre-purchase questions and resolution speed.
- Third-party intent feeds: topic consumption, review site engagement, and research surges.
- Firmographic and market signals: hiring for relevant roles, technology stack changes, funding announcements, leadership moves, and new locations—often strong B2B behavioral intent signals when aligned to your ICP and product.
Data quality and coverage considerations:
- First-party data is most reliable and precise because you control its collection and event definitions. Use it as the backbone of your models and workflows.
- Second-party and third-party data expand reach beyond your owned properties but are noisier; weight them appropriately and validate with first-party behaviors.
- Prioritize consented, well-instrumented events. Inconsistent event naming or missing timestamps degrade downstream modeling.
- Build a signal catalog: assign each signal a weight and a half-life, define positive and negative intent, and map signals to funnel stages.
KatalystIQ centralizes multi-source buying signals, enriches leads with firmographics and company insights, and unifies them in one profile. This enables consistent scoring and targeted outreach without stitching the data by hand.
Feature Engineering and Signal Processing
Turning raw events into features that represent intent is where much of the predictive power is created. Well-designed features make intent scoring machine learning models simpler, more accurate, and easier to maintain.
Sessionization and identity stitching:
- Sessionization groups events into meaningful visits or interaction windows. Common defaults use a 30-minute inactivity threshold, but adjust by channel and product. Consider cross-tab behavior, multi-day research, and server-side events that don’t align to pageviews.
- Identity stitching ties activity to a person and, in B2B, to an account. Use deterministic keys where possible (logged-in user IDs, verified emails, CRM IDs) and supplement with probabilistic methods only when you have consent and a clear governance process. Roll features up at both user and account levels to capture individual and buying committee patterns.
Temporal features that capture momentum:
- Recency: time since last high-value event (e.g., pricing page view, trial activation).
- Frequency: counts within rolling windows (e.g., 7/14/30 days) by event type.
- Inter-event intervals: shrinking gaps often signal rising intent.
- Decay-weighted aggregates: apply exponential decay so recent actions matter more than older ones.
- Cadence features: time-of-day/day-of-week preferences tied to response likelihood.
Composite features and path patterns:
- Ratios: product-view-to-cart rate, pricing-visit-to-form-fill rate, documentation-to-pricing ratio.
- Stage progression: first-time pricing visit followed by integration doc view within 48 hours can indicate technical validation.
- Intent momentum: the rate of change in a decay-weighted intent score over time; spikes can trigger priority routing.
- Cross-channel blends: email click followed by on-site comparison within 24 hours versus isolated clicks.
Behavioral embeddings for richer context:
- Embeddings compress high-dimensional sequences (pages, events, topics) into dense vectors that capture similarity. For example, visitors whose sequences embed close together often share needs or readiness. You can learn embeddings from event co-occurrence or sequences and feed them into downstream models to improve generalization.
Handling sparse categories and missing data:
- High-cardinality categories (SKUs, URLs, UTM values) benefit from hashing, frequency capping, or target encoding with strict leakage prevention (fit encodings on training folds only).
- Group rare categories into “other” to stabilize estimates; preserve the top N categories with distinct behavior.
- Treat missingness as information: include “is_missing” flags, and use sensible defaults or learned imputations. A missing firmographic field can itself indicate low data quality or a net-new prospect.
- Guard against outliers (e.g., auto-refresh or bot-like events) with caps, filters, and anomaly flags.
Operational tips:
- Maintain feature parity between training and serving; mismatches cause drift and poor real-time performance.
- Version feature definitions and keep them human-readable; small definitional changes can materially shift scores.
- Monitor feature freshness and null rates; sudden changes often signal instrumentation issues rather than behavior shifts.
KatalystIQ’s AI Lead Qualification combines engineered behavioral features with firmographic enrichment and buying signals to produce actionable scores and segments. Teams can then automate outreach, route opportunities, or trigger personalized sequences the moment intent crosses a threshold.
Models and Algorithms Employed
With features engineered and behavioral intent signals prepared, the next decision in purchase intent detection is which modeling approach best fits your data, latency needs, and operational constraints.
Logistic regression (and other linear models). These are strong baselines for intent scoring machine learning. They train fast, are straightforward to interpret, and produce calibrated probabilities with proper regularization and post-processing. They work well when you’ve already encoded non-linearities through composite features (e.g., recency×frequency) and have modest feature sets. They struggle when interactions are complex or sequences drive most of the signal.
Tree-based models (random forests and gradient-boosted trees). Tree ensembles naturally capture non-linearities and feature interactions, handle missing values, and cope with many sparse categorical indicators. Random forests are robust and easy to parallelize but can be less sharp for ranking and probability calibration. Gradient-boosted trees are often the top choice for tabular behavioral data, offering strong ranking power, support for monotonic constraints (useful for features like “more visits should not decrease intent”), and efficient training. Calibrating their outputs (e.g., with isotonic regression) improves decision thresholds for outreach and bidding.
Sequence models (RNNs, temporal CNNs, transformers). When the order and timing of events matter—pages viewed, email touches, ad interactions—sequence models can exploit that structure better than aggregates. RNNs/LSTMs or temporal CNNs work well for short to medium sequences. Transformers handle longer histories and irregular time gaps using time-delta embeddings. These models demand more data, careful regularization, and typically more serving compute. They shine in high-volume digital products and can also aid B2B pipelines when recent micro-behaviors (e.g., viewing pricing then comparing plans) are pivotal. A pragmatic pattern is hybridizing: gradient-boosted trees on aggregates plus a lightweight sequence model capturing the last N events.
Representation learning. Learn embeddings for products, content, or accounts (e.g., via matrix factorization or item2vec-style methods). These embeddings summarize affinities and feed into tree-based or deep models, improving generalization for sparse catalogs and new content.
Time-to-event modeling. Beyond point predictions, survival or hazard models estimate likelihood of purchase within a time horizon, helping prioritize urgency and cadence. These models require carefully defined censoring and consistent observation windows.
Ensembles and hybrid rule+ML stacks. In B2B, strict business rules (ICP fit, compliance, account ownership) often gate eligibility. A rule layer can pre-filter or override edge cases, after which an ML ranker orders candidates by near-term intent. Blending models (e.g., a gradient-boosted tree with a calibrated logistic model) can boost stability. Segment-specific models (by industry or size) improve lift when behaviors differ markedly.
KatalystIQ supports this hybrid approach in practice: you can combine buying signal rules (e.g., funding or hiring surges) with AI Lead Qualification models, then drive Workflow Automation that routes only high-confidence, high-urgency leads to sales or personalized outreach.
Labels Training Data and Evaluation
Defining labels, assembling reliable training data, and choosing the right metrics are make-or-break steps for AI purchase intent systems.
Label definition and windows
- Positive labels. A common definition is “purchased within X days of the scoring moment.” In longer B2B cycles, substitute purchase with a decisive downstream action such as “opportunity created” or “contract signed.” Choose X to match the business decision horizon: what you plan to do with the score over the next 7, 14, 30, or 90 days.
- Observation/outcome windows. Separate the observation window (behavioral data you allow the model to see) from the outcome window (where you check for conversion). Add a small gap to reduce leakage (e.g., avoid including a demo-booking event that occurs minutes before the outcome is recorded).
- Negatives. Define as “no purchase within X days.” To avoid biasing the model to recent traffic, ensure negatives are sampled across time and segments.
Proxy and staged labels
- When actual purchase rates are low or infrequent, use proxies such as demo booked, trial started, proposal requested, or sales-qualified status. You can train a series of models—engagement → qualification → opportunity → purchase—and multiply probabilities to get an end-to-end purchase estimate.
- For ad use cases, consider intent-to-engage labels (e.g., reply within 7 days) when purchase is too delayed to optimize media quickly.
Class imbalance handling
- Positive classes often sit between 0.5% and 10%. Use class weights or focal loss where supported. Keep all positives, downsample negatives to a manageable ratio, and correct for sampling in calibration if needed.
- Stratify by cohort (industry, region, segment) to maintain representative distributions.
Data splitting and leakage control
- Use time-based splits: train on earlier periods, validate/test on later periods. This mirrors production.
- Split by entity to prevent the same person/account appearing in both train and test sets.
- Enforce point-in-time correctness so features don’t include future knowledge (e.g., post-outcome CRM updates).
Evaluation metrics
- Ranking and classification. Prioritize Precision-Recall metrics over ROC when positives are rare. Track PR AUC, precision@k, recall at fixed precision, and lift in the top deciles. For sales ops, “meetings booked per 100 outreaches” is a practical precision proxy.
- Calibration. Well-calibrated scores let you set thresholds and forecast pipeline. Use reliability plots, Brier score, and expected calibration error.
- Business impact. Convert model scores to expected value by segment: Expected profit = p(buy) × revenue − (1 − p(buy)) × outreach cost. Pick thresholds that maximize expected value, not just F1.
Operationalizing the feedback loop
- Close the loop by pulling outcomes from your CRM or billing system to refresh labels and retrain on a schedule. Use holdouts to track true incremental lift over time.
KatalystIQ’s CRM & Sales Integrations make it straightforward to feed downstream outcomes (e.g., stage changes, closed-won) back into your labeling pipeline and then route top-scored accounts into AI Personalization or AI SDR workflows.
Real Time Scoring Infrastructure and Integration
Delivering scores where and when they matter is as important as model accuracy. A practical, low-latency stack for purchase intent detection typically includes:
- Event ingestion. Stream web/product activity, marketing interactions, CRM updates, and third-party intent feeds. Normalize IDs and attach timestamps on arrival.
- Identity and session services. Maintain person/account keys, link devices and emails, and compute rolling session aggregates needed by the model.
- Online feature store. Serve point-in-time-correct features with strict TTLs for recency and frequency counters, last-seen timestamps, and segment memberships. Keep online and offline stores schema-aligned.
- Model serving. Expose a low-latency API or function that transforms incoming events into features and returns a score within defined SLOs (e.g., p95 < 100–200 ms) with autoscaling and circuit breakers.
- Decisioning and orchestration. Translate scores to actions: add to audiences, trigger sales tasks, personalize web/app content, throttle outreach, or push bids to ad platforms.
- Batch scoring for slower rhythms. Nightly or hourly jobs can score accounts for territory planning, nurture prioritization, or budget allocation.
Integration points
- CDP and personalization engines for on-site messages, paywalls, or recommendation variations based on intent tiers.
- CRM for routing, ownership, and task creation tied to thresholds (e.g., high-intent within 14 days → immediate outreach).
- Ad platforms for audience inclusion/exclusion and bid adjustments that reflect near-term purchase probability.
Online experiments and safe deployments
- A/B testing. Randomly assign users/accounts to champion vs. challenger models or to different thresholds. Measure lift in qualified meetings, revenue per contacted account, and cost per opportunity.
- Canary releases. Send a small percentage of traffic to a new model, monitor latency, error rates, and guardrail business metrics, then ramp progressively.
- Shadow mode. Score events with a new model without acting on them to compare distributions and debug feature parity.
- Fallbacks. If real-time features are unavailable, fall back to a cached score or rule-based logic to maintain continuity.
KatalystIQ operationalizes this flow by combining Buying Signals Detection, AI Lead Qualification, and Workflow Automation. For example, when a target account shows a hiring spike and recent pricing-page views, KatalystIQ can score the opportunity, create a CRM task, and trigger AI Personalization across email and LinkedIn—without manual handoffs.
Privacy Compliance and Ethical Risks
Purchase intent detection works best when it’s both effective and respectful. Build trust with privacy-by-design and responsible modeling practices.
Consent-first data collection
- Obtain clear consent for first-party tracking and honor user choices. Avoid using events or identifiers collected without a valid legal basis.
- Prefer first-party data and company-level signals in B2B; treat personal data conservatively and document your lawful basis for processing.
Data minimization and retention
- Collect only signals required for intent use cases. Aggregate or hash identifiers where possible and avoid storing sensitive attributes unrelated to sales decisions.
- Set retention windows aligned to sales cycles and purge or archive data after it ceases to be operationally useful.
Anonymization and security
- Pseudonymize personal identifiers in analytical stores and restrict access via role-based controls. Encrypt data in transit and at rest.
Bias and fairness checks
- Exclude protected attributes and clear proxies from features used for modeling. Evaluate performance and calibration across segments (industry, company size, region) to detect disparate impact.
- Implement outreach safeguards: frequency caps, cooling-off periods, and do-not-contact enforcement to prevent over-targeting.
Transparency and user control
- Provide clear notices about data usage and give users channels to opt out or request deletion. Maintain audit trails for how scores are generated and used in workflows.
KatalystIQ runs on a Secure Cloud Platform and integrates with your CRM and email platforms, allowing teams to align automations with existing consent and communication preferences managed in those systems. Your legal and compliance teams should review data flows, retention settings, and outreach policies to ensure they meet applicable regulations and your company’s standards.
Measuring Impact and Operational KPIs
Once your models are live, the work shifts to proving incremental value, not just model accuracy. Tie purchase intent detection outputs to business outcomes and instrument your systems so you can move from anecdotes to repeatable gains.
Conversion and revenue impact
Segment customers by score bands (e.g., deciles) and compare conversion rate, average order value, revenue per user, and win rate. Look for monotonic lift: higher intent bands should outperform lower ones.
Measure sales velocity: time-to-first-meeting, stage-to-stage progression, and overall cycle length. Intent-driven prioritization should shorten cycle time for high-score leads.
Track operational efficiency: meetings per rep-hour, cost per SQL/MQL, and outreach-to-meeting rate when sequencing is guided by intent.
Incremental lift and attribution
Use randomized holdouts: withhold intent-driven actions (e.g., accelerated outreach or higher ad bids) for a small random control group. The difference between treatment and control is your incremental lift.
Apply stratified holdouts by score band to ensure fair comparisons across propensity levels.
Consider time-based or geo-based controls when randomization isn’t feasible, then validate comparability before inferring lift.
For multi-touch journeys, use simple, defendable attribution models (position-based or time-decay) and validate with lift tests. Save advanced methods (e.g., uplift modeling) for later maturity.
Operational monitoring and model health
Prediction quality: track calibration (do 0.7 scores convert ~70% relative to their band?), score distributions (watch for collapse toward the mean), and stability of rank ordering across cohorts.
Data pipelines: monitor feature freshness, null rates, schema changes, and upstream outages; set alerts for missing or delayed signals.
Drift detection: watch input drift (feature distribution shifts) and output drift (score distribution shifts). Use simple thresholds first; evolve to statistical alerts as you mature.
Latency and coverage: measure end-to-end scoring latency and the percentage of users/leads who receive a score. Coverage gaps often hide in edge channels or new markets.
Continuous improvement
A/B test decision policies, not only models: thresholds, routing rules, and outreach sequences tied to intent bands. Small policy changes often yield large gains.
Retraining cadence: schedule periodic retraining (e.g., monthly or quarterly) and add event-driven retrains when drift or seasonality is detected.
Human-in-the-loop: capture rep feedback on false positives/negatives inside the CRM to guide error analysis and feature updates.
How KatalystIQ helps: By pushing intent scores and buying signals into your CRM and outreach tools, KatalystIQ makes it straightforward to create scored cohorts, route them via workflow automation, and log downstream actions. Teams can then calculate conversion lift, velocity, and revenue per user in their analytics stack while keeping the operational workflow centralized.
Implementation Roadmap and Best Practices
A focused 60–90 day pilot is the fastest route to value. Keep scope tight, choose a few high-impact actions, and set clear success criteria.
Pilot project checklist
Objectives: Define the business decision the score will power (e.g., lead prioritization for SDRs, bid adjustments in retargeting, or triggered account-based outreach).
Success metrics: Pick 2–3 primary KPIs (e.g., conversion rate lift in top two deciles, meetings booked per 100 contacts, cycle time reduction) and a guardrail (e.g., unsubscribe or spam complaint rate).
Data: Confirm available first-party signals (web, CRM, email), consent coverage, and any second/third-party intent sources. Create a minimal data dictionary with definitions and refresh cadences.
Labels: Define positive events and attribution windows (e.g., purchase or SQL within 30 days of score). Document exclusions to prevent leakage.
Experiment design: Establish treatment vs. holdout, randomization unit (lead/account), and sample size targets.
Integration: Map where scores will live (CRM fields, audiences, personalization engine) and what actions will fire at each threshold.
Timeline: Include time for data access, model training, QA, soft launch, and results readout.
Team roles and stakeholders
Product/RevOps owner to align objectives, coordinate teams, and own change management.
Data scientist/ML engineer to build the model, features, and evaluation.
Data engineer to productionize pipelines and ensure reliability.
Marketing/Sales operations to implement routing, sequences, and ad/audience sync.
SDR/AE lead to provide frontline feedback and refine operating playbooks.
Privacy/compliance to review consent, retention, and usage policies.
Executive sponsor to unblock resources and approve go/no-go at key gates.
Tooling and vendor evaluation criteria
Data connectivity: Prebuilt connectors to your CRM, email platform, ads, and web analytics; support for APIs and webhooks.
Real-time and batch: Ability to compute features and scores with low latency where needed, plus reliable batch jobs.
Explainability and observability: Access to feature importance, score distributions, drift alerts, and lineage.
Workflow orchestration: Trigger channel actions (e.g., sequences, ads, messaging) based on score thresholds.
Security and governance: Role-based access, audit logs, consent handling, and regional data controls.
Cost and scalability: Transparent pricing, ability to scale to more signals and segments without re-architecture.
Common mistakes to avoid
Label leakage: Using future-looking fields (e.g., opportunity status) in training data.
Confusing model AUC with business impact: Always validate with holdouts and policy tests.
Ignoring class imbalance: Calibrate thresholds and use stratified evaluation by segment.
Static playbooks: Failing to adapt outreach cadence or content by intent band.
No feedback loop: Not capturing rep disposition reasons, which slows improvement.
Training–serving skew: Mismatched feature definitions between offline training and production scoring.
Compliance gaps: Missing consent lineage or unclear data retention policies.
Where KatalystIQ fits: KatalystIQ shortens setup by supplying cross-channel buying signals, AI-led lead qualification, and CRM integrations. Teams can define score-triggered workflows, personalize outreach using AI, and stand up reusable Lead Machines for specific segments. For faster time-to-value, KatalystIQ Velocity provides hands-on implementation support to configure knowledge bases, connect systems, and operationalize your pilot.
Frequently Asked Questions
Accuracy varies by data richness, label quality, and use case. Well-instrumented funnels with clear labels often support strong rank-ordering (top score bands convert materially higher than lower bands). Treat accuracy as fitness for purpose: if score-guided actions lift conversions or shorten cycles in controlled tests, the model is accurate enough for that decision.
Signals closest to commercial intent usually matter most: high-depth product/content views, pricing page activity, repeat return visits, request-for-quote or trial flows, and high-engagement email or ad interactions. For B2B, firmographic changes and account-level behavioral intent signals (e.g., multiple stakeholders researching) are especially predictive.
Define a positive event tied to your goal (e.g., purchase or SQL) and a look-forward window (e.g., within 30 days of the score). Use exclusion windows to avoid leakage (e.g., don’t count actions that happen before the score is computed). When positives are rare, add proxy labels (trial start, demo requested) or staged labeling to increase training signal.
They require consent-first data collection, clear purposes for processing, and respect for data subject rights. Use data minimization, retention limits, and anonymization where feasible. Maintain records of consent and provide opt-out mechanisms. Consult your legal team for requirements in your jurisdictions.
Yes, with sufficient history you can model both probability and timing. Common approaches include survival analysis or sequence models that estimate hazard (likelihood of conversion over time). Expect wider uncertainty bands; use timing predictions to pace follow-ups and budgets rather than to set exact dates.
Run controlled tests where intent-driven actions are applied to a treatment group and withheld from a randomized control group. Compare conversion, revenue per user, and cycle time. Segment by score bands to assess monotonic lift. Validate results across cohorts (channels, geos, segments) before scaling.
Poor labels, training–serving feature mismatches, unaddressed class imbalance, stale features, and data drift are frequent culprits. Operationally, generic outreach that ignores score bands and lack of feedback loops will mute gains even with a good model. Regular monitoring, retraining, and policy experimentation keep performance healthy.